TL;DR: Timothy is a self-hosted AI assistant I built in Go for one user: me. It gives me one chat interface over every model provider I use, memory in my own database, a ledger of every token spent, and long-running work that continues after I close the tab. The design follows three rules.
First, deterministic code orchestrates, and each model call does exactly one thing. Go decides which model to call, what goes into the prompt, whether a tool may run, and when to stop. A model call answers one question and returns data.
Second, services are split along trust boundaries, not features. The gateway is the path to every model provider, sandboxd alone holds the Docker socket, and brain is the only service with a public API.
Third, one Postgres holds all state. Sessions, memories, vectors, the cost ledger, missions and encrypted secrets share one database with pgvector. No broker, no separate vector database.
This series is written as a design reference: the requirements, the options I compared, and why I chose what I chose. The code is on GitHub.
The problem
What does a personal assistant need that a chat tab does not give?
I use several model providers, each in its own tab with its own history. None shows what a conversation cost across providers, none remembers what I told the others, and none works unless I am typing. Timothy replaces those tabs:
| Requirement | Detail |
|---|---|
| Users | Exactly one. One bearer token guards everything. |
| Providers | Any number, configured at runtime as rows, not code. Hosted APIs and local models side by side. |
| State | Conversations, memory, configuration and costs live in my database. |
| Cost | Every model call lands in a ledger. An unknown price is stored as unknown, never guessed. |
| Unattended work | Missions and automations run without me, and stop for approval before anything destructive. |
| Footprint | One Docker Compose file on one machine. No Kubernetes, no broker. |
Challenge 1: who decides what happens next?
Should the model run the show, or the code?
| Option | How it works | Why not (or why) |
|---|---|---|
| A. Agent framework | A library supplies the loop, memory, tool calling and prompt templates | Prompts hide behind abstractions. When a turn goes wrong I need the exact bytes sent. |
| B. Model as orchestrator | A planning model picks tools, sub-agents and models, and decides when work is done | It loses coherence, defends its own mistakes and declares unfinished work done. Every safety rule becomes a prompt it can be talked out of. |
| C. Go orchestrates, each call does one job | Plain Go calls the gateway. Each model call has one purpose and returns data that code validates | No framework to lean on; the plumbing is mine to write and test. |
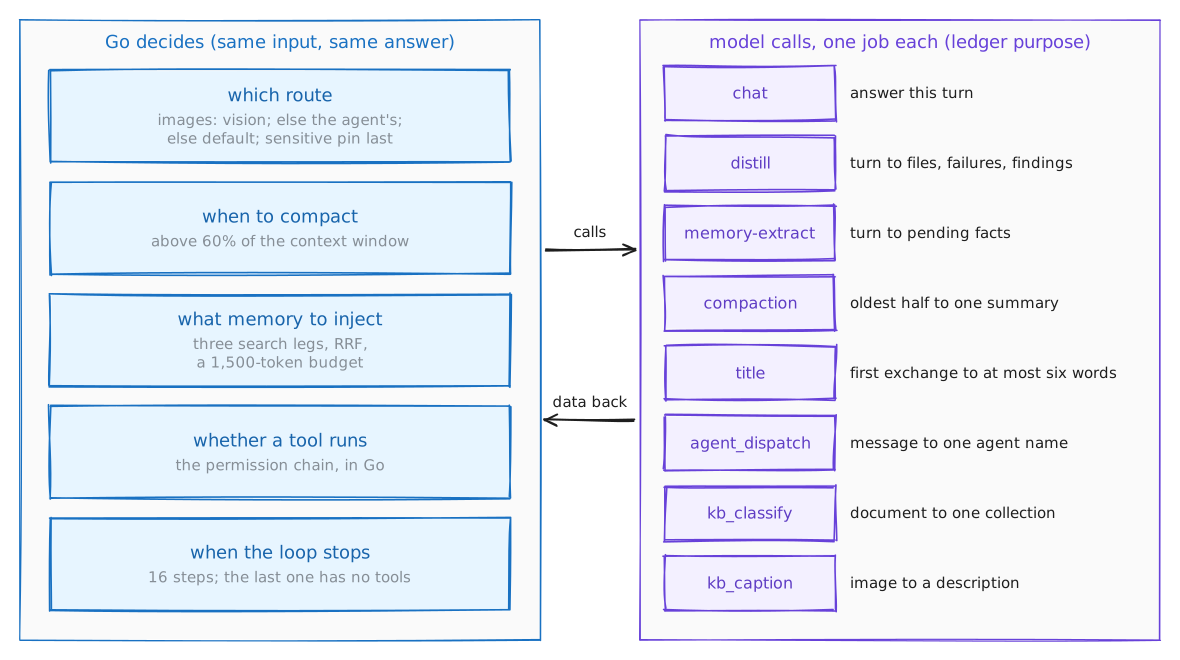
I chose C. The deciding argument: a prompt can be persuaded and an if statement cannot. Routing, compaction, memory selection and tool permission must give the same answer every time, so they are Go. Models get the reading, summarising and writing, one narrow job per call.
- One agent loop, in one place. brain owns the only tool loop; the gateway never loops. The loop has a 16-step ceiling, warns the model one step early, and sends the last step with no tools.
- Every side call is labelled. Distillation, memory extraction, compaction summaries, titles, agent dispatch and knowledge-base filing are separate calls, each with its own
purposein the cost ledger.
Challenge 2: where do the seams go?
One process, a service per feature, or something else?
| Option | How it works | Why not (or why) |
|---|---|---|
| A. One binary | Everything in one Go process | Simplest to run, but the process reading untrusted web pages and model output would also hold every provider key and the Docker socket, which is root on the host. |
| B. A service per feature | Chat, missions, automations and the knowledge base as separate services over a broker | Many deploy units for one user, and the seams follow features, which change, not privileges, which do not. |
| C. Split where privilege or runtime differs | A few Go services, each holding one dangerous thing, plus sidecars for Python-only tools | More containers, and internal calls cross the network. |
I chose C. A seam earns its place when it keeps a key, a socket or a runtime away from code that handles untrusted input, and brain handles untrusted input (web pages, email, tool results, model output) all day.
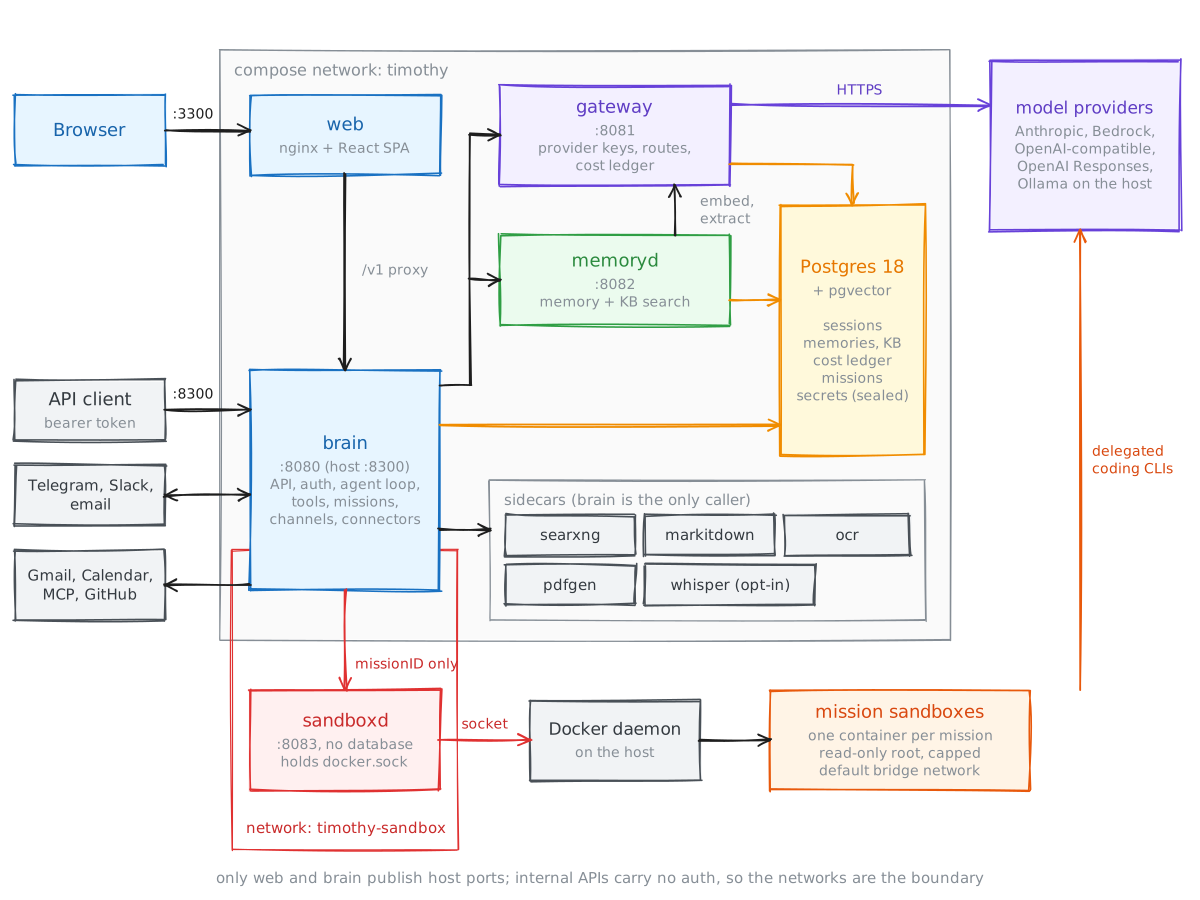
Figure 2: Every service in the compose file, where only web and brain publish ports and sandboxd shares a network with brain alone. Open full-size diagram
| Service | Owns | Never does |
|---|---|---|
| brain | public API, agent loop, tools, missions, channels, connectors | touch the Docker socket |
| gateway | providers, routing, failover, normalized streaming, cost ledger | run tools or loop |
| memoryd | memories, knowledge base, hybrid search | hold a provider key (it embeds through the gateway) |
| sandboxd | the Docker socket, one container per mission | connect to the database |
| sidecars | searxng, markitdown, ocr, pdfgen, whisper (opt-in) | touch the database |
- Internal APIs carry no auth, on purpose. They publish no host ports. A shared secret would have to live in brain’s environment, exactly what the split assumes may be compromised, so the network is the boundary.
- sandboxd sits on its own network,
timothy-sandbox, with brain as the only other member. Its API takes a mission ID, never an image, mount or container name, and its container runs read-only with every capability dropped. - The gap I accepted. brain also holds the master key, because connectors, channels and delegated coding CLIs need credentials of their own. Every model call from Timothy’s own loop uses a key that exists only in the gateway, but brain is not key-free.
Challenge 3: where does state live?
One database, or the right store for each shape of data?
| Option | How it works | Why not (or why) |
|---|---|---|
| A. A store per shape | Postgres for rows, a vector database for embeddings, a broker for events | Three backups, three failure modes, and a sync job between rows and vectors that will drift. |
| B. A database per service | Each service owns its own store | No shared transactions. brain and the gateway both write the cost ledger, for example. |
| C. One Postgres with pgvector | Every table in one database; vectors and full-text columns sit on the same rows as the text | One instance to keep healthy; when it is down, everything is. |
I chose C. At one user’s scale Postgres is good enough at every job here, and one database means one backup and transactions that span what would otherwise be separate systems.
- Vectors live beside their text.
memoriesandkb_chunkseach carry avector(1024)column with an HNSW index and a generatedtsvectorcolumn, so hybrid search needs no sync job. - An inbox table instead of a broker. A side effect that must survive a crash (a finished mission, a cron boundary, a webhook) goes into
eventsin the same transaction as its cause. A drainer delivers it after commit, with bounded retries. - Append-only where history matters.
session_events,mission_eventsandmemoriesare never updated in place; a correction is a new row.
How one chat request flows
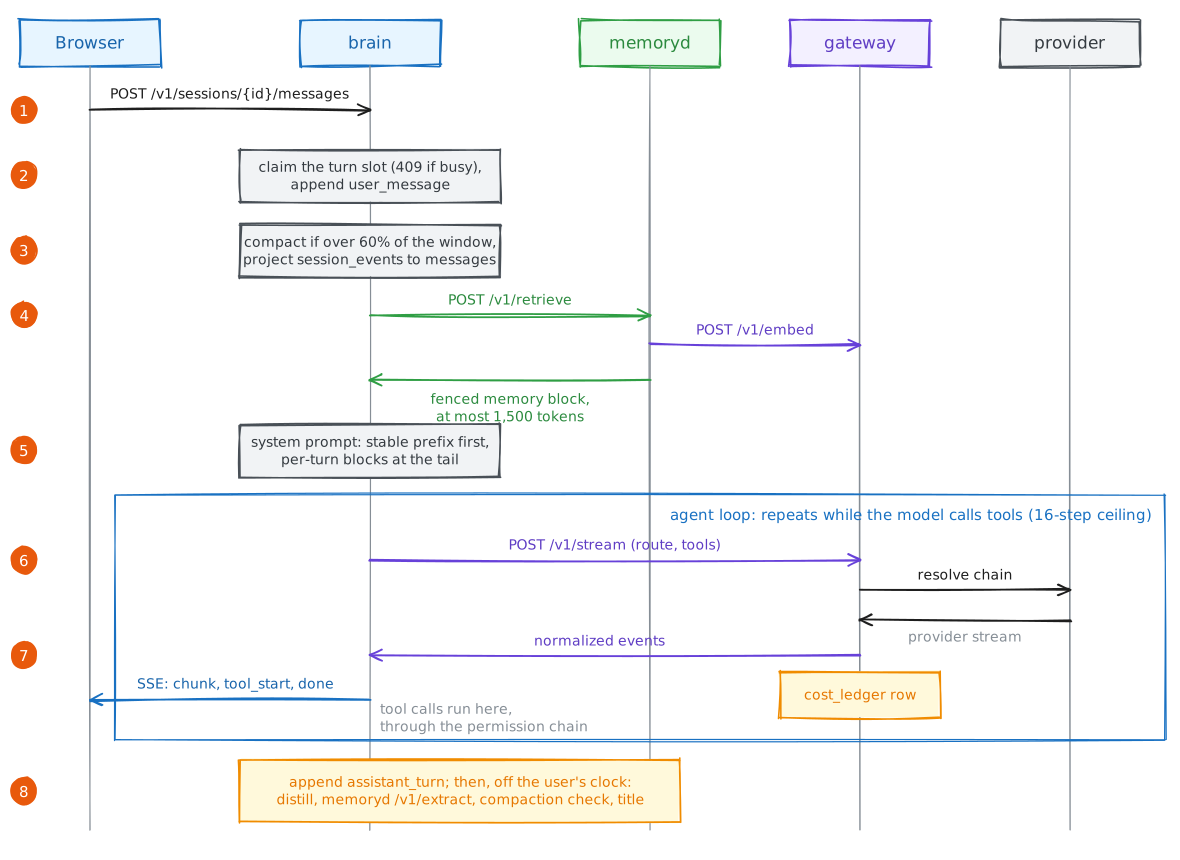
- The browser sends
POST /v1/sessions/{id}/messages; the web container’s nginx proxies/v1to brain. - brain claims the session’s single turn slot (a second request gets
409) and appends auser_messageevent. The turn now belongs to the session, not the HTTP request: closing the tab does not stop it. - brain compacts if the context passed 60% of the model’s window, then projects
session_eventsinto model messages. - memoryd embeds the query through the gateway and returns a fenced memory block of at most 1,500 tokens.
- brain assembles the system prompt: a stable prefix first, so provider prompt caches keep hitting, and per-turn blocks at the tail.
- The loop calls
POST /v1/streamon the gateway with a route name. The gateway resolves it to a provider chain, streams, and writes acost_ledgerrow per attempt. - Normalized events flow to brain and on to the browser over SSE. Tool calls run in brain through the permission chain, then the loop calls again.
- brain appends the
assistant_turn. Distillation, memory extraction, a compaction check and a first-turn title run after the answer is durable.
Degrade, never crash
What happens when a dependency is not there?
One machine restarts in odd orders: Postgres comes up late, a sidecar is off, a provider is down. Every Go service serves /health before its database is reachable. The pool reconnects with backoff, migrations retry, and /health reports degraded with a reason instead of the container restart-looping.
Optional features follow the same rule: without the OCR sidecar a knowledge-base image gets no description rather than a failed ingest, and an unset WHISPER_URL leaves transcription unmounted. Only configuration that cannot fix itself fails fast: a missing master key stops the gateway at boot.
What’s next
Part 2 opens the gateway: providers as data, routes as roles, one event stream for every provider, and the bright line that decides when failover is still safe.